Powering AI-led research through simulation
The short story
Consider a Friday evening. A food order arrives from a mall in the city center. One driver is nearby; another is finishing a drop-off and will be available shortly; a second order from the same mall may or may not appear in the next two minutes. Dispatch the nearby driver now, or hold briefly for a batching opportunity? The decision window is short.
A fulfillment marketplace makes these decisions continuously. Each one is small. Across a city, those decisions determine whether your dinner arrives hot and whether a driver’s hour is well spent.
And that is one decision. There are dozens more: how far to look for a driver, when two orders are worth combining, which of three waiting trips gets the one free bike, how long to keep trying before giving up. These decisions interact, and the setting that is right for Friday at seven is wrong for Tuesday at two. Together they define a space of possible strategies far larger than anyone could exhaustively explore.
We sample only about a dozen points in that space each year. Not for want of ideas: implementing each strategy costs weeks of engineering, and a production experiment takes weeks more to judge. Some questions have no production answer at all. Nobody can run last Saturday again with twenty percent fewer drivers. We were never short of compute resources, and never short of data. We were short of attempts.
So we built sim-rs, a simulator that makes each attempt take minutes, and connected agents that run experiments on it.
sim-rs is self-contained: it requires no production services or databases. The dispatch lifecycle runs in one compiled program alongside a separate dispatch service that is spawned locally and operates offline. Historical booking and driver data go in as plain files, together with a configuration describing the strategy to test. Simulated bookings, trips, drivers, and a single metrics report come out. Processing one city-day of marketplace activity takes tens of minutes, from raw input to finished report. One command in, one report out: a workflow as practical for a software agent as for an engineer.
That compact contract is what makes the simulator AI-friendly. Agents can change bounded components, run reproducible experiments, receive verdicts they cannot alter, and help keep both production logic and behavioral models current.
Building blocks
The essential components
To model a marketplace, the simulator needs four core concepts:
- Bookings: requests to move something (a passenger, a meal, a parcel), represented in one format regardless of the business vertical.
- Drivers: simulated workers with a location, a shift, a vehicle, and a queue of work.
- Trips: units assigned to drivers, containing one booking or several batched into a multi-stop route.
- Ticks: simulated time, advancing in fixed steps. Nobody waits in real time.
At each tick, the simulator runs the following sequence:
- Demand arrives. Historical (or synthesized) bookings whose time has come enter the pool.
- Supply moves. Drivers come on shift, advance along routes, go idle, and reposition.
- Pre-dispatch cancellations are applied. Cancellation models, including survival-analysis models trained on real behavior, determine which bookings leave the pool.
- Dispatch happens. Bookings are batched into trips, trips are matched to drivers by an optimization solver, and a recycling step decides, for each trip, whether to send it now, hold it, or split it back into bookings and try again later.
- Post-dispatch cancellations are applied. These include passenger and driver cancellations.
- Outcomes are recorded. Every booking, trip, and driver outcome is written to the run outputs.
Crucially, this is a closed loop: today’s dispatch decisions change where drivers end up, which changes what’s possible next tick. That feedback produces second-order effects that a static replay, one that scores historical decisions without updating future supply, cannot show. Supply may dry up in a hot zone, or one bad dispatch rule may cascade into a wave of cancellations.
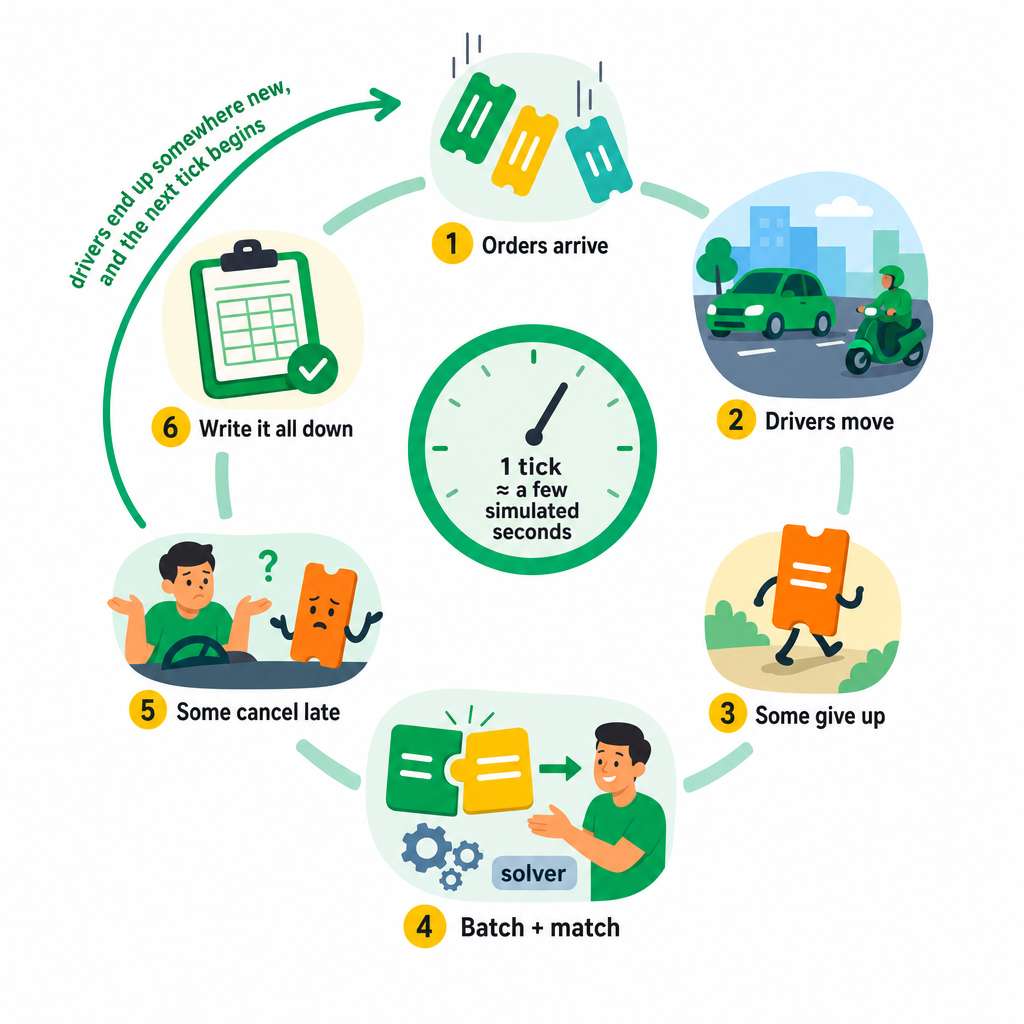
That loop is only the mechanism. Making it a lab takes three further properties: configurability; reproducibility and auditability; and reliable comparison.
1. Interchangeable stages. The major dispatch stages are pluggable. Batching, allocation, cancellation, routing, driver movement, and recycling are each exposed through an interface with interchangeable implementations selected by configuration. This turns a fixed pipeline into an experimental platform: the component under study can be swapped while everything around it stays unchanged. The same mechanism determines which marketplace is being simulated. Ride-hailing, food delivery, parcel delivery, or all three sharing one driver pool are configuration choices within the same codebase, not separate simulators.
2. Self-contained runs. Each experiment is a small, portable package containing its configuration files, input data, source revision, metrics report, and detailed outputs. Anyone holding that package can recreate the setup, whether a reviewer, teammate, agent, or the original author six months later. The report identifies the configured components and headline metrics, while the supplementary per-booking, per-trip, and per-driver outputs let reviewers recompute those metrics and investigate unexpected outcomes without relying on separate notes or systems.
3. Experiments inside the simulation. Production marketplaces have experimentation platforms, so our simulator ships with one too. Experimentable fields can define multiple treatment arms assigned through the same time-based switchbacks, spatial splits, or cell-and-hour schemes used in production. Each booking records its resolved arm for traceability. Running these A/B/n comparisons together exposes every arm to the same demand, drivers, marketplace dynamics, noise, and biases. By reproducing both the conditions and assignment design of a marketplace experiment, simulated insights are more likely to translate into effects observed in production.
Automating the research cycle
Agents do two jobs here, and both need the same environment: searching for strategies that beat the incumbent, and keeping the simulator sufficiently faithful for that search to mean something.
Searching for better strategies
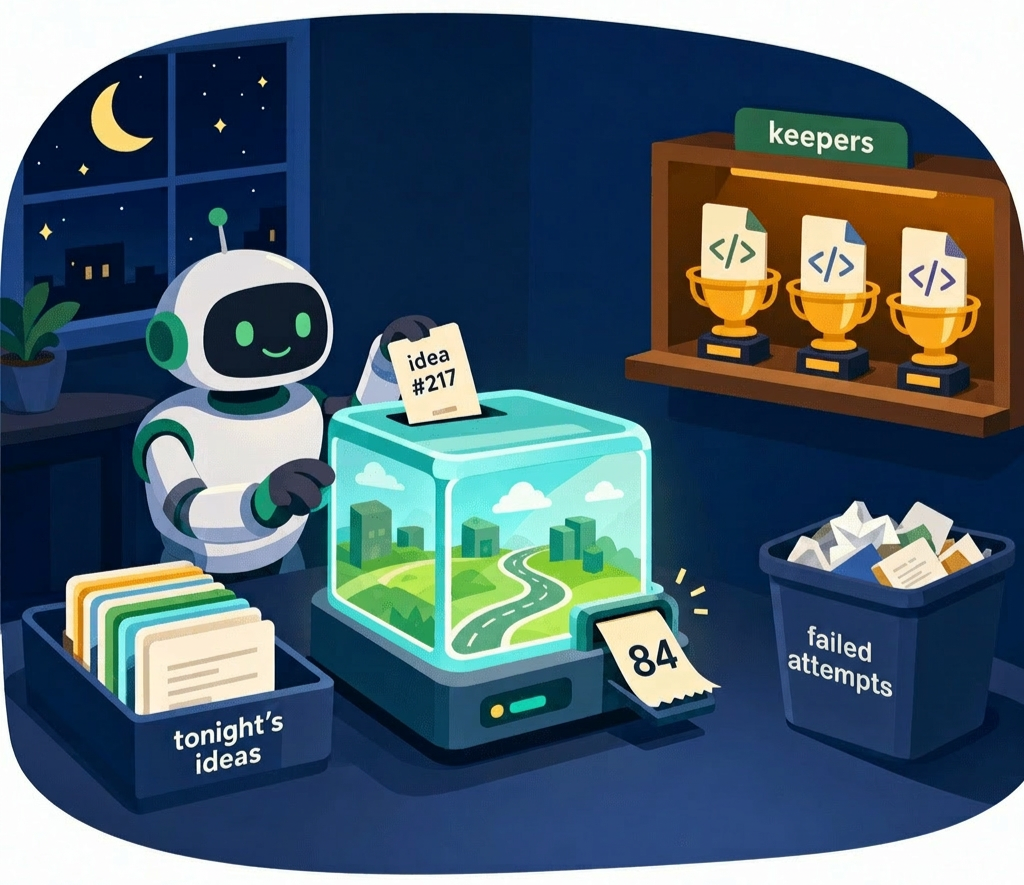
We connect agents to that interface through autoresearch, an automated loop that runs the research cycle end to end. An agent proposes a change, implements it in source code, tests it, and acts on the verdict. A candidate survives only if it improves the target metric and passes every required check; otherwise it is rolled back and the loop continues. The objective may be a marketplace outcome such as orders-throughput or a software measure such as execution time. What matters is a repeatable command-and-metric contract that both humans and agents can use.
The first failure mode we encountered was specification gaming. Given a target and a loophole, an agent may find the shortest path to the number rather than the improvement we intended. Ours discovered that changing fields used by pre-dispatch cancellation could reduce cancellations and raise completion without improving a single dispatch decision. The metric moved; nothing real had improved. Rather than relying on instructions alone, we built four safeguards into the environment:
- Core data is immutable. Modules under test may change only the state exposed by their interfaces. An attempt to manipulate protected fields fails to compile instead of producing a misleading result.
- The verdict is computed, not judged. The simulator computes its own metrics, which the agent can read but not redefine. Executable checks apply calibrated tolerance bands, verify equivalent outputs where required, and run the tests. The agent never judges its own work.
- Changes are scoped, checked, and reversible. Each experiment runs on its own branch within a declared writable scope, which is checked against the resulting diff. The grading machinery remains outside that scope, regressions cost only a discarded branch, and every surviving change is bounded enough to review in full.
- Changes are checked at two levels. It first rejects changes that violate type contracts, ownership rules, interface boundaries, or concurrency requirements. The evaluation harness then applies checks suited to the objective: performance work must preserve expected outputs, while strategy experiments must satisfy domain constraints and outcome thresholds.
The speed that matters is the speed of an adaptive research loop, not simulation runtime alone: each iteration uses previous results to propose the next change, then implements, compiles, runs, scores, and decides whether to keep it. The simulator returns a verdict in milliseconds for benchmarks or tens of minutes for a full-day replay, while autoresearch carries each verdict into the next attempt without human handoffs. This turns an overnight run into a connected sequence of evidence-driven experiments, with the safeguards above ensuring that faster iteration compounds reliable evidence rather than mistakes.
One outcome is the familiar purpose of simulation: discovering better marketplace strategies. When asked to explore trip-recycling policy, the loop turned an emerging human intuition into a concrete rule: hold batched orders only as long as service-level deadlines permit, maximizing the chance that another nearby order joins the trip. Because the result is human-readable code, engineers can review, audit, and deploy it like any other pull request.
The same machinery also improves the simulator itself. Over several nights of unattended operation, we aimed the agents at two hot paths in its dispatch logic: the checks that decide which drivers are eligible for a trip, and the pass that adjusts the cost of every driver-and-trip pairing before the solver chooses an assignment. Across roughly 150 logged experiments, three out of four attempts failed to build or were rejected by later gates. The eligibility checks ended up about 10 times faster, and the cost pass about 24 times faster. Because these paths run repeatedly in every replay, improvements compound across subsequent research. Faster and more efficient runs enable testing of more ideas across more markets and dates, repeat runs to separate signal from noise, and validate results more rigorously. Shorter runs also tighten the feedback loop from verdict to next proposal, so improving the instrument accelerates and strengthens every search performed with it.
Execution time is only one possible objective: pointing the same machinery at orders-throughput changes the research question, not the loop itself. Regardless, whatever the objective, the result is only as trustworthy as the simulator behind it. An agent can optimize only the world it is given; if that world has drifted from production, a faster loop will merely produce misleading answers sooner.
Keeping the simulator faithful
A simulator is a claim about the world: that this is how the system behaves and that this is how the people within it respond. Both halves of that claim decay. Production logic changes continuously, while models of passenger and driver behavior grow stale as new product features reshape how people act. A simulator that has drifted from the world produces misleading insights and innovations that fail in production. So the second job we give agents is to keep the simulator faithful.
The system half is a translation problem, and coding agents are particularly good at it. An agent can read a component’s production implementation and implement equivalent logic behind the simulator’s corresponding interface, translating directly from source code rather than from a written description that may already be stale. The result remains a candidate until parity checks show that it matches the production behavior being modeled.
The behavioral half cannot be translated, because no source file tells us how a passenger will behave. It must be inferred from what people actually do. Here, we redirect the same autoresearch loop from dispatch-code optimization to behavioral modeling. It proposes, fits, and scores candidate models, exploring which features predict cancellation and how their effects should be represented. The test is not only how closely a model explains its training data, but also how well it generalizes to held-out data. A model that fits last Tuesday perfectly and next Tuesday poorly does not make the simulator more faithful; it makes the lab more confidently wrong.
The pieces are simple: a realistic marketplace model, swappable parts, repeatable experiments, honest scoring, and an easy way to undo failures. Together, they give agents a safe place to test and improve ideas. Everyone is racing to give AI a bigger brain. We got further by giving it a better lab: a place where it can try a thousand ideas, be wrong cheaply, and receive an honest verdict.
Join us
Grab is Southeast Asia’s leading superapp, serving over 900 cities across eight countries (Cambodia, Indonesia, Malaysia, Myanmar, the Philippines, Singapore, Thailand, and Vietnam). Through a single platform, millions of users access mobility, delivery, and digital financial services, including ride-hailing, food delivery, payments, lending, and digital banking via GXS Bank and GXBank. Founded in 2012, Grab’s mission is to drive Southeast Asia forward by creating economic empowerment for everyone while delivering sustainable financial performance and positive social impact.
Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!